
Prompt extractor · Comparison
Prompt extractor vs CLIP Interrogator
Last updated
Use CLIP Interrogator when you work in Stable Diffusion 1.5 or 2.x and want the style and artist tags that model family responds to. Use a vision-model prompt extractor for everything else: it describes layout, light, and camera in full sentences, which is what Flux, Midjourney, GPT Image, and SDXL follow best. Many people run both and merge them.
Want to skip ahead? The free prompt extractor reads any JPEG, PNG, or WebP and gives you a text prompt and a JSON prompt. No account needed.
How do the two tools differ?
They answer different questions. CLIP Interrogator asks "which words from my lists match this picture?" A prompt extractor asks "how would I describe this picture to an image model?" The first is great at vocabulary. The second is better at describing what is actually going on in the frame.
| CLIP Interrogator | Prompt extractor (Reprompt) | |
|---|---|---|
| How it works | A BLIP caption, then CLIP ranks lists of artists, mediums, movements, and style words against the image | A vision-language model looks at the image and writes the prompt in sentences |
| Output | One line: caption, then comma-separated tags | A detailed paragraph, plus structured JSON on Reprompt |
| Best for | Stable Diffusion 1.x and 2.x, finding style and artist terms | Flux, Midjourney, GPT Image, Nano Banana, and SDXL |
| Layout and light | Weak. It rarely says where things are or where light comes from | Strong. Camera angle, lens, light direction, and composition are spelled out |
| Setup | Hugging Face Space, Colab, or a local install with a GPU | Upload in the browser, no account |
| Runs offline | Yes, if you install it | No, it calls a hosted model |
What does a prompt extractor return for a real photo?
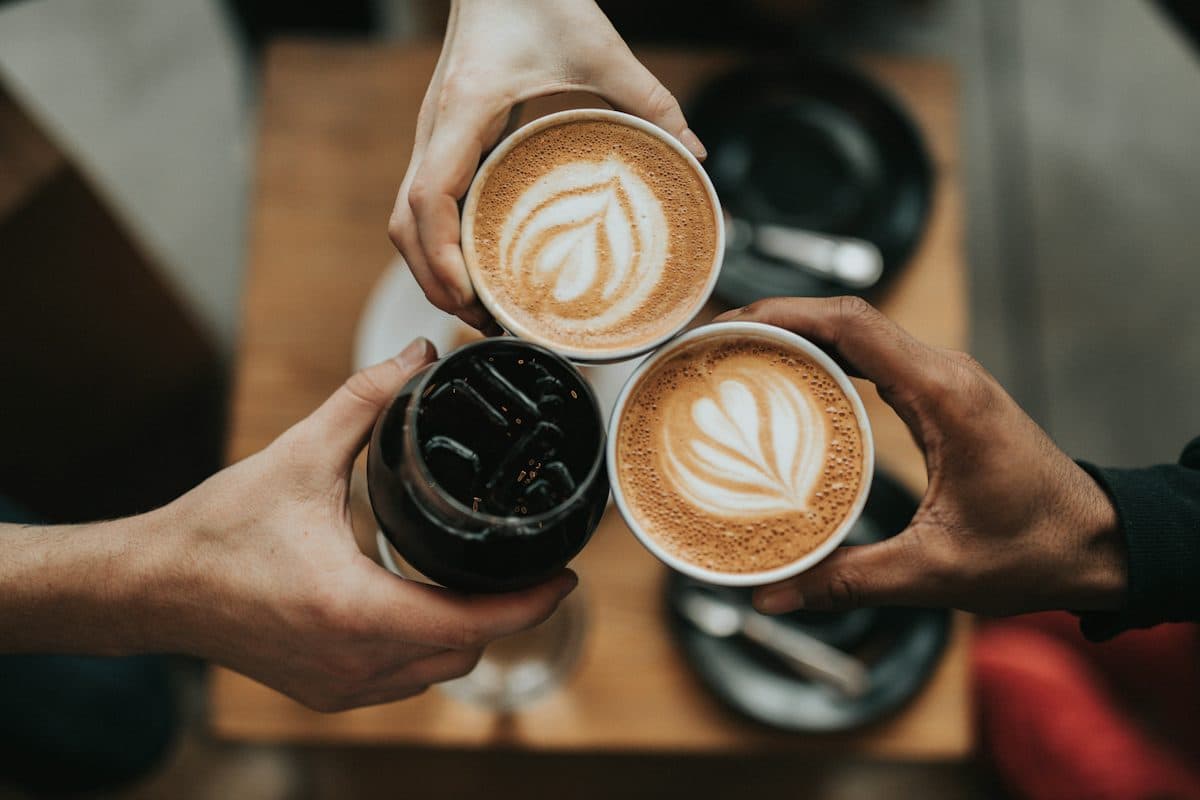
This is the Reprompt prompt extractor's output for the photo above, captured 2026-10-06 and only trimmed of a leading label:
Text prompt
A high-angle, top-down shot capturing a celebratory "cheers" moment with three beverages held together over a wooden table. The subject includes two cups of hot latte, each featuring intricate, symmetrical heart-shaped foam latte art, and one glass of iced black coffee filled with dark, square ice cubes. Three distinct hands—one with fair skin holding the top latte, one with light skin holding the iced coffee, and one with tan skin holding the right latte—bring the drinks together in the center. The photography style is modern, intimate, and documentary-lifestyle. The lighting is soft, natural, and diffused, creating a warm, cozy atmosphere with deep, rich shadows and high-contrast textures on the foam and coffee. The color palette consists of warm earthy tones, deep browns, creamy whites, and muted wood grains. In the background, slightly out of focus, are two black ceramic saucers with silver spoons, resting on a textured light oak wooden tabletop. The composition is a tight, symmetrical triangle focused on the meeting point of the drinks. The image features a shallow depth of field, with the focus razor-sharp on the foam patterns and the ice, while the edges of the frame softly blur. Cinematic quality, shot on a 35mm lens, f/2.8, professional color grading, ultra-detailed texture, 8k resolution. Aspect Ratio: 3:2.
It names the angle (top-down), the arrangement (a triangle of hands), the light (soft and diffused), and even the cups' latte art. Those are the things CLIP Interrogator tends to skip.
What does CLIP Interrogator output look like?
It returns a single line: a short BLIP caption, then a run of comma-separated terms ranked by CLIP. The shape looks like this (a format illustration, not a run on our photo):
Typical format
a [short caption of the scene], by [artist name], [medium], [art movement], [flavor term], [flavor term], trending on artstation
Those trailing terms are the useful part. They tell you which style words the CLIP model links to the image, and in SD 1.5 adding one of them can shift the look more than a full sentence would. The caption itself is usually too short to rebuild the scene.
Which should you pick for your model?
- Stable Diffusion 1.5 or 2.x: CLIP Interrogator for style tags, then add layout lines from an extractor.
- SDXL: extractor first. The Stable Diffusion prompt generator also writes the negative prompt.
- Flux: extractor, as a plain caption. See image to prompt for Flux and Stable Diffusion.
- Midjourney: extractor or
/describe, then flags. See how to find the prompt of a Midjourney image. - GPT Image or Nano Banana: extractor, ideally the JSON version so you can change one field at a time.
Questions people ask
What is CLIP Interrogator?
An open-source tool by pharmapsychotic that guesses a prompt for an image. It writes a caption with BLIP, then uses OpenAI's CLIP to pick the artist, medium, movement, and style words that best match the picture. It was built for Stable Diffusion and is still popular on Hugging Face and inside Automatic1111 extensions.
Is CLIP Interrogator still worth using?
For SD 1.5 work and for discovering style keywords, yes. Its tags come from the same CLIP model family that older Stable Diffusion versions were trained with, so those words carry weight there. For newer models that read full sentences, a vision-model extractor usually gives a prompt you need to fix less.
Which CLIP model should I pick?
Match it to the checkpoint. ViT-L-14/openai pairs with Stable Diffusion 1.x, and ViT-H-14/laion2b_s32b_b79k pairs with Stable Diffusion 2.x. The tool's own readme lists these pairings.
Can I use both?
Yes, and it works well. Take the extractor's paragraph for subject, layout, and light, then borrow two or three style tags from CLIP Interrogator if you want a specific look in Stable Diffusion.